Martin Kelly, Founder of Botonomy AI, has automated enough of his own SEO work to know exactly which parts bite back — usually at 2am, usually in a bulk meta rewrite. He now builds pipelines with approval gates and sleeps fine.
Most articles about SEO automation are tool listicles with no author name on them. This one isn’t. The pipeline I’m describing below runs in production across 9+ e-commerce brands, where organic traffic rose 43% on average (Bloom Search Marketing, 2024–present), and I’m going to show you the stack, the stages, the quality gates, and the parts I deliberately refused to automate.
In short
SEO automation means using software and AI agents to run repetitive search tasks, like crawling, rank tracking, clustering, and reporting, without manual effort. SEO is still worth it in 2026, and beginners can absolutely do it themselves with a spreadsheet below a few hundred URLs; roughly 90% of a serious pipeline is deterministic code, with Google penalizing scaled content abuse, not automation itself, and execution tasks still need human approval.
What Is SEO Automation?
SEO automation is the use of software, scripts, and AI agents to execute repetitive search optimization tasks — crawling, keyword clustering, rank tracking, internal linking, schema generation, content briefs, and reporting — without manual intervention.
Key takeaways
- Tier 1 monitoring (GSC API → BigQuery) is close to 100% automatable.
- Tier 3 execution needs a human approval gate or it ships something embarrassing.
- Google penalises scaled content abuse, not automation as a method.
- Below ~200 URLs and 2 posts a month, a spreadsheet beats a pipeline.
What is automation in SEO? Automation in SEO means handing repeatable, rule-based search tasks to scripts and APIs — rank tracking, crawl alerts, schema markup, reporting — so humans spend their hours on strategy, editorial judgement, and the decisions that actually carry risk.
Here’s what it isn’t. It isn’t “set and forget SEO” — every pipeline I’ve built drifts within about 90 days as Google changes something or a client changes their CMS. And it isn’t the same thing as pointing an LLM at a keyword and publishing whatever falls out. That’s content generation, and it’s the fastest route to a manual action I know of.
A real stack touches a specific set of components: the Google Search Console API, GA4, BigQuery, Screaming Frog or Sitebulb for crawls, Semrush or Ahrefs for market data, Surfer SEO for on-page scoring, Python and Scrapy for anything custom, and n8n or Zapier holding it together. What it operates on is also specific: schema.org structured data, Core Web Vitals, log file analysis, keyword cannibalization, and internal linking.
One 2026 wrinkle that changes the job. Automation now has to cover AI search visibility — whether ChatGPT, Perplexity, and Google AI Overviews cite you — not just blue-link rankings, and almost nobody’s monitoring layer has caught up to that yet.
SEO Automation vs. AI SEO vs. Programmatic SEO
Three terms, used interchangeably by people selling all three, with completely different risk profiles.
| Term | What it actually means | What it automates | Typical tooling | Main failure mode |
|---|---|---|---|---|
| SEO automation | Deterministic execution of repeatable tasks | Reporting, crawl scheduling, rank pulls, alerting | n8n, Zapier, Python, GSC API | Logic silently drifts from reality; nobody notices for months |
| AI SEO | LLMs applied to judgement-heavy work | Clustering, intent classification, briefs, entity mapping | Surfer SEO, custom GPT pipelines | Hallucinated recommendations delivered with total confidence |
| Programmatic SEO | Page inventory generated from a structured dataset | Template-driven page creation at scale | CMS APIs, structured data sources | Thin, duplicative pages caught by scaled content abuse policy |
The distinction matters because the blast radius differs. A broken automation sends you a wrong number. A hallucinating AI step sends you a wrong strategy. A bad programmatic build puts 40,000 near-identical pages on your domain and invites a site-wide quality problem.
Most working pipelines are all three stacked — deterministic plumbing, model calls where judgement is needed, templated output at the end. If you’re also optimizing for answer engines, it’s worth understanding how generative SEO changes what you optimize for, because entity coverage behaves differently from keyword coverage.
How SEO Automation Works: The Three Tiers of Automation Depth
Automation depth, not tool count, determines what you actually get back. You can own eleven subscriptions and still do everything by hand.
Tier 1 — Data collection and monitoring. Rank tracking, crawl alerts, indexation and 404 monitoring, and a GSC → BigQuery pipeline. Google documents the Search Console API and the GA4 BigQuery export directly, so this layer is verifiable, cheap, and boring in the best way. Near-fully automatable.
Tier 2 — Analysis and recommendation. Keyword clustering, cannibalization detection, internal link suggestions, log file analysis, Core Web Vitals regression flags. Scheduled Screaming Frog or Sitebulb crawls feed this. My internal estimate: 70–80% automatable, with a human reviewing the output before anyone acts on it.
Tier 3 — Execution. Schema injection, programmatic page generation, bulk meta rewrites, auto-publishing. n8n orchestrating a CMS API does the work. This tier needs a human approval gate, permanently, or it will eventually publish something that makes you wince in a client meeting. If you want the mechanics, here’s how agentic workflows chain these steps together with gates between each hop.
One more thing separates a pipeline from a pile of scripts: a scheduler, a state store, and failure alerts. Without all three, you don’t have automation — you have cron jobs failing quietly at 3am.
Inside Our SEO Automation Pipeline: What We Actually Built
Eight stages, running continuously. Here’s the order and the stack.
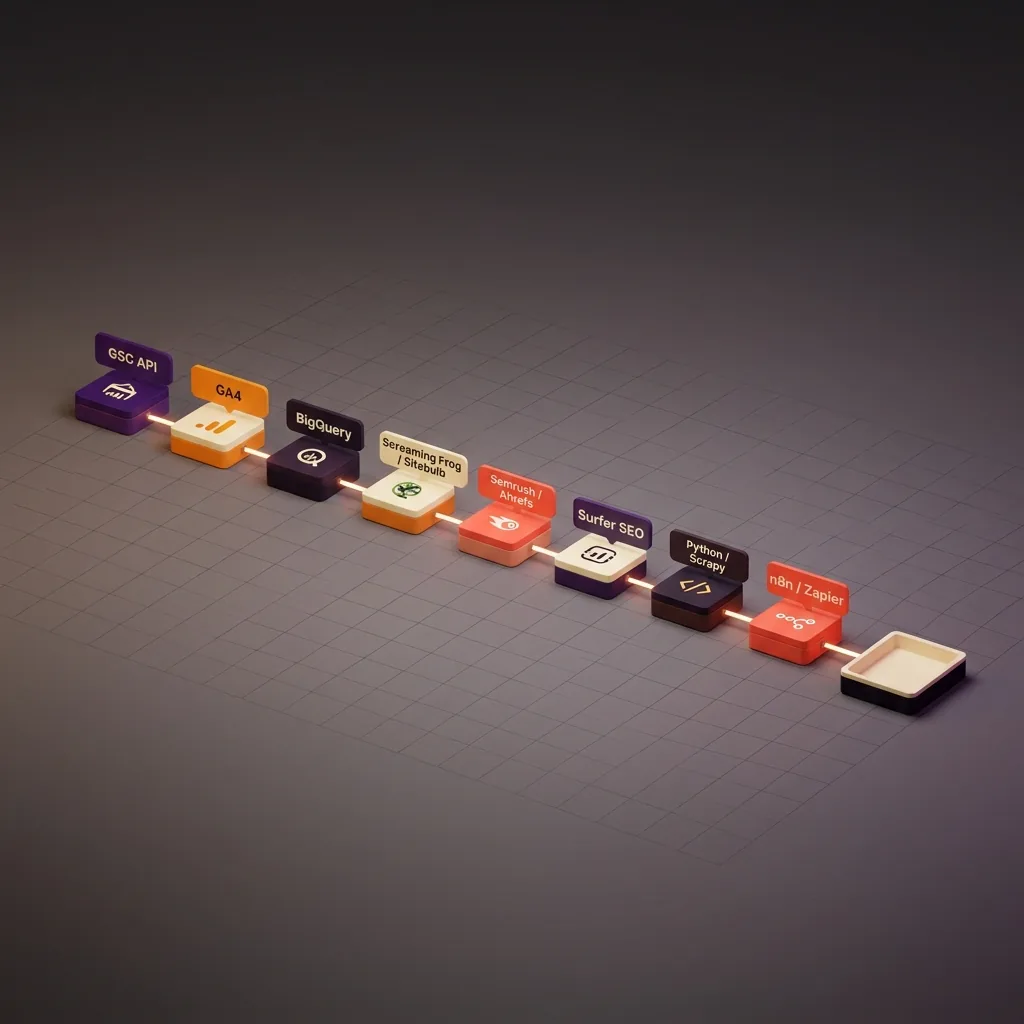
1. Keyword and SERP ingestion. Semrush and Ahrefs exports plus live GSC query data land in BigQuery nightly. Airtable holds state — what’s been processed, what’s queued, what failed.
2. Clustering and intent classification. Python handles the embedding and clustering maths. A model call classifies intent per cluster, because “best X” and “X vs Y” split on nuance that rules get wrong.
3. SERP and AEO fan-out analysis. We pull the live SERP, then separately check whether ChatGPT, Perplexity, and Google AI Overviews cite the topic and who they cite. This is the stage most pipelines skip entirely.
4. Brief generation. Entity coverage, subquery targets, schema type, word count, internal link candidates. Deterministic assembly, model-written where the brief needs a judgement call.
5. Draft. Model call, tightly constrained by the brief.
6. QA gates. Four of them, hard-failing: schema validation against schema.org, internal link relevance scoring, a cannibalization check against every existing URL on the domain, and human approval before anything publishes.
7. Publish. n8n hits the CMS API. Nothing reaches this stage without a human clicking approve.
8. Feedback loop. Performance data flows back into GSC and BigQuery, and clusters get re-scored against actual results rather than against what we hoped would happen.
Scheduled Screaming Frog crawls run alongside all of this — that’s the automated SEO audit system we run on every site, checking technical health independently of the content pipeline.
The architecture principle: roughly 90% of the logic is deterministic code, roughly 10% is model calls. LLMs get used where judgement is genuinely required. Everywhere else, rules are cheaper, faster, and don’t invent things.
Measured numbers, labelled honestly. Cross-brand reporting dropped from roughly 18 hours a month to under 2 — internal estimate across our own client pipelines. Brief production runs 20–30 a week. Scheduled crawls cover full URL inventories in the 40,000-page range without anyone opening a laptop.
What I refused to automate: link acquisition, editorial judgement on E-E-A-T, and redirect decisions. Each one is a place where being wrong is expensive and being slightly slower costs nothing.
Benefits of SEO Automation: Is It Worth It in 2026?
Hours reclaimed on reporting
Manual rank and traffic reporting across multiple brands ate roughly 18 hours a month before we automated it. Now it’s under 2 — internal estimate, our pipelines, not a study.
Crawl coverage at volumes humans skip
Manual auditing breaks down somewhere around 5,000 URLs. Past that, people sample, and sampling is where the broken canonical on 800 product pages hides. Scheduled crawls don’t sample.
Consistency across templated pages
Schema.org markup and metadata stay uniform across thousands of pages because a template writes them, not a person on a Thursday afternoon with four other tasks open.
Detection latency measured in hours
Indexation drops, 404 spikes, and Core Web Vitals regressions surface within hours instead of at the next monthly audit. The gap between “it broke” and “we noticed” is where revenue leaks.
Research at economically impossible scale
Clustering 50,000 keywords into entity groups by hand isn’t slow. It’s not happening at all.
Is SEO still worth it in 2026? Yes, but the ROI case has moved. Pew Research Center’s 2025 analysis of Google search behaviour found users were markedly less likely to click a result when an AI-generated summary appeared. Position one matters less; being the entity that gets cited matters more. That argues for broader coverage and cleaner structured data, not for giving up.
The honest cost line: automation pays off above a threshold. Below roughly 200 URLs and a couple of posts a month, you’ll spend more time maintaining pipelines than doing SEO.
What SEO Automation Can’t Do (And Where It Backfires)
Five ways I’ve watched this go wrong:
- Thin auto-generated content published at volume
- Automated link building
- Blind auto-redirects from pattern-matching rules
- Unreviewed bulk meta rewrites
- Quietly outsourcing editorial judgement to a model
Google’s spam policies documentation names scaled content abuse and link spam explicitly. Read the actual policy, not someone’s blog summary of it — the wording is more specific than most people assume, and specificity is what keeps you on the right side of it.
Auto-redirects deserve their own warning. A rule that collapses distinct URLs into one destination looks tidy in a spreadsheet and destroys intent-matched landing pages in practice. You lose the conversions before you lose the rankings.
The governance rule: every Tier 3 action needs a diff, a log, and a rollback path. Automation without observability is how a site breaks silently for six weeks.
And the editorial boundary is simple. A model cannot supply first-hand experience, and first-hand experience is precisely what E-E-A-T measures.
One last risk nobody mentions — automated reporting that nobody opens is worse than manual reporting someone argues with.
How We Know This
The pipeline above was built and iterated from 2024 to now, running across 9+ e-commerce brands plus our own properties. Figures labelled “internal estimate” come from our own time tracking and client pipelines, not from published research.
SEO Automation FAQs
Is SEO automation safe?
Safe at Tiers 1 and 2 — monitoring and analysis carry almost no downside risk. Risk concentrates in Tier 3 execution without approval gates, where bulk actions hit live pages. Add a human checkpoint before publish and the safety question largely disappears.
Does Google penalize automated SEO?
No. Google penalizes scaled content abuse and manipulative link schemes, both named in its spam policies — the method of production isn’t the issue, the output quality and manipulative intent are. Automated reporting, crawling, and schema generation are entirely fine.
What percentage of SEO can be automated?
My tier-weighted estimate: about 95% of Tier 1 monitoring, 70–80% of Tier 2 analysis with review, and maybe 50% of Tier 3 execution with gates. Blended, that’s roughly 70% of task volume — but closer to 30% of the decisions that matter. Estimate, not a study.
Is SEO automation worth it for small sites?
Below roughly 200 URLs, 2 posts a month, and 100 tracked keywords, free tools plus a spreadsheet win. Pipeline maintenance has a fixed cost that small sites can’t amortise. Revisit the question when publishing cadence or URL count doubles.
Can I do SEO myself? Can a beginner do SEO?
Yes to both, in this sequence: set up Google Search Console, add one crawl tool, add one rank tracker, then automate reporting first and execution last. Free options cover most of it — GSC API, Google Looker Studio, and Screaming Frog’s free tier up to 500 URLs. Here’s a breakdown of the SEO audit tools worth scheduling once you outgrow the free tiers.
Build the Pipeline, Not the Tool Stack
The single most important thing here: automate monitoring first, recommendation second, and execution last — with a human gate on anything that writes to a live site.
- Use deterministic code wherever rules work; reserve model calls for genuine judgement.
- Give every Tier 3 action a diff, a log, and a rollback path.
- Pick the one task eating the most hours per month and automate its monitoring layer this week, before you buy a single new tool.
That last point is the whole decision. Not which platform — which task.
If you want to see this pipeline running rather than described, book a walkthrough and I’ll show you the stages, the gates, and the parts that still need a human.